Make the submission prove itself before a person reads it.
Google just paused an open source bug bounty because machine-written reports buried the people reading them. If your support queue, claims inbox, or seller applications run on human reading time, you're next in line.
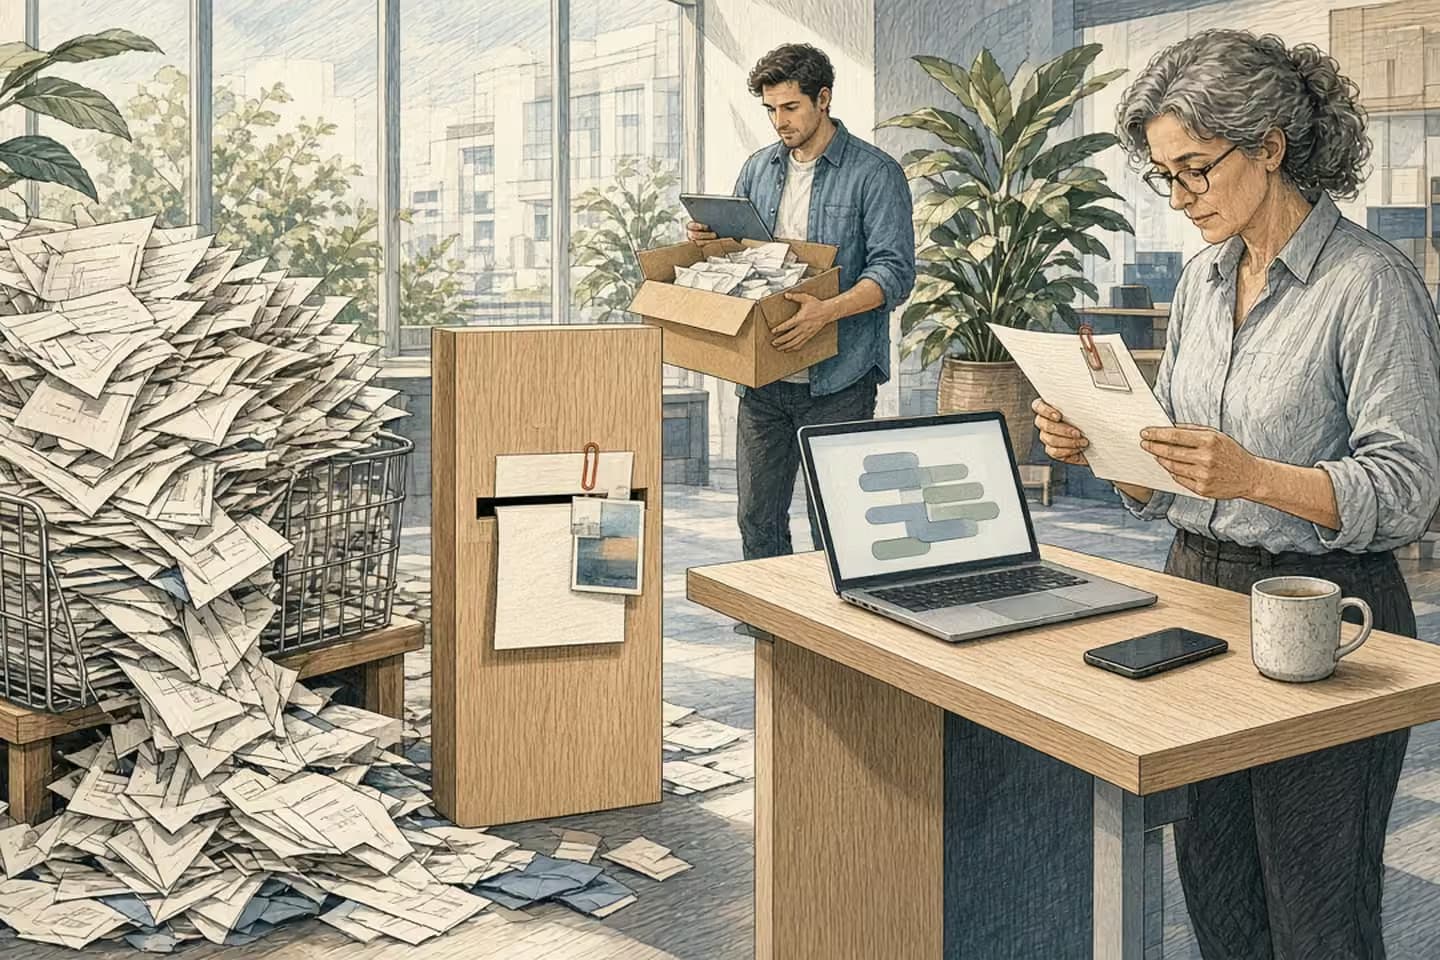
When AI makes submissions nearly free to produce, any intake where a person reads every item will flood. Before you pause the program or hire more reviewers, ask each submitter for one piece of evidence your system can check on its own, such as an order that matches a record, steps that reproduce, or a photo of the real item. Check it before a human looks, tell people what is missing instead of silently rejecting them, and sample the rejected pile every week.
What actually happened?
On October 4, TechCrunch reported that Google has paused its Open Source Software Vulnerability Rewards Program, the bounty that pays researchers for finding security bugs in Google's open source projects. The pause took effect October 1, and Google says it will share an update in the first quarter of 2027.
Google's own explanation is one sentence: the pause is due to a significant rise in automated submissions, "the vast majority of which are not valid." Coverage citing Tom's Hardware adds that engineers and maintainers were overwhelmed by reports that were wrong or simply hallucinated.
That's a security story on the surface. Underneath, it's an operations story, and it isn't only Google's. A bounty program is an intake queue with a reward attached. Somebody outside writes something, and somebody inside has to read it carefully enough to decide whether it's real. The writing half just got close to free. The reading half didn't move.
Does this matter if we don't run a bug bounty?
Probably more than you'd think. Look at anything in your business where a stranger can send you a thing and a trained person has to evaluate it:
- Support tickets and warranty or return claims
- Seller or vendor applications on a marketplace
- Responses to an RFP or a grant program
- Public comments on a proposed rule or permit
- Job applications, partner referrals, damage reports
Each of these used to have a natural brake. Writing a convincing claim took time, so most people only wrote one when they had a reason. That brake is gone. A single person, or a single script, can now produce a hundred plausible, well-formatted, completely wrong submissions in the time it used to take to write one.
If there's money, a refund, a listing, or attention at the end of your queue, you're already on the list of places this will happen. The question is whether you notice it as a slow rise in reviewer overtime or as the week your team stops being able to answer real customers.
Writing a submission got cheap. Reading one didn't.
Isn't that what the spam filter is for?
Spam filters are good at catching junk. This isn't junk. The problem submissions read well. They use the right vocabulary, cite plausible details, and are polite. A filter that looks at the words will wave them through, because the words are fine.
What's missing is truth, and you can't see truth in the prose. A reviewer finds out a report is invalid by doing the expensive part: trying to reproduce the bug, looking up the order, opening the photo and noticing it shows a different product. That's exactly the time that's getting eaten.
So the fix isn't a smarter text classifier sitting in front of the same queue. Plenty of teams will try that first, and some will try an AI model to judge AI-written claims. It can help sort, but it has the same blind spot: it reads the words. You need the submission to carry something the words can't fake.
So what should a submission have to prove?
Pick one piece of evidence that's cheap for a real submitter to provide and expensive for a fake one, then have your system check it before any person reads the rest. A few examples of what that looks like:
- A return or warranty claim includes an order number and the email on the order, and the system confirms they match a real purchase inside the return window.
- A bug report includes steps or a test case that your build system can actually run and watch fail.
- A damage claim includes a photo the system can match against the SKU, the delivery address, or the shipment record.
- A seller application includes a business registration or tax ID that a lookup service can confirm.
- A public comment is tied to a verified contact, even if the name isn't published.
Notice what these have in common. None of them asks the submitter to write more. They ask for one fact that lives in a system somewhere, and the check is mechanical. A real customer has their order number. A fabricated claim usually doesn't, and if it does, now you've learned something worth a person's time.
The human reviewer still does the judgment work. They just stop doing it on items that couldn't pass a lookup.
We made the same distinction in a very different setting. On Sutton|Place, a platform for private-market deals, a seller's claim doesn't become a confirmed fact just because it's in the system. The software keeps what someone said separate from what was checked, who checked it, and what's still pending. An intake gate is a smaller version of that idea: a submission is an assertion until something verifies it.
How the work moves
Check one fact before a person reads
- Submission arrives
Claim, ticket, report, application, or comment, with one required piece of evidence.
- System checks the fact
Order matches a record, steps run, ID resolves, photo matches the shipment.
- Fail: say what's missing
Plain reply naming the gap. No silent drop.
- Pass: person reviews
Reviewer spends judgment time only on items that cleared the lookup.
- Weekly sample
Someone reads a slice of rejections to catch real people the gate turned away.
Won't this turn away real people?
It can, if you build it carelessly. Three rules keep it honest.
Tell people what's missing. A submission that fails the check should get a plain reply saying what to add, not a silent drop. Real people fix it. Scripts mostly don't come back.
Keep a slow lane. Someone who lost their receipt or can't produce a test case should have a way through, even if it takes longer. Put that lane behind something a script won't bother with, like a short call or a follow-up question that depends on their own details.
Sample the rejected pile. Once a week, have someone read twenty or fifty items the gate turned away. If real customers are in there, the check is wrong, and you'll find out before they post about it. This is the only way to know your gate's false rejections, so don't skip it because the queue finally feels calm.
There's a pricing question hiding here too. If your program pays per accepted item, like a bounty or an affiliate referral, think about whether the reward should depend on the evidence and not just the report. Paying for volume is what makes the flood worth sending.
Decision guide
Filtering words versus checking facts
| Consideration | Gate on a verifiable fact | Filter on the text |
|---|---|---|
| Plausible fake | Fails when the order, test, or ID doesn't check out. | Passes because the writing is fine. |
| Reviewer time | Spent on items that cleared a lookup. | Spent proving each item false by hand. |
| Real person who fails | Told what to add, with a slow lane. | Often dropped without knowing why. |
| How you know it works | Weekly sample of rejections and reviewer hours. | The queue feels quieter, or it doesn't. |
When is pausing the right call?
Sometimes. If you can't separate good submissions from bad ones without a full expert review, and the program is paying out or burning your best people's week, stopping is more responsible than pretending the queue is fine. Google did it the reasonable way: it said why and named when you'll hear more.
But a pause is the last tool, not the first. Most intake queues have at least one fact they could check before a person reads, and most teams haven't asked for it because, until recently, they didn't need to.
If you want to try this on your own queue this week, keep it small:
- Count what came in over the last month and how many hours your reviewers spent on it.
- Pull fifty recent items and mark which ones turned out invalid, and what the reviewer had to do to find out.
- Name the one fact that would have caught most of them, and where that fact already lives.
- Put that check in front of the queue, with a clear reply when it fails and a slow lane for exceptions.
- Track reviewer hours and the weekly sample of rejections for a month.
That's usually an integration and a small workflow change, not a new platform. It's the kind of business process automation we build: a lookup in the right system, at the right point in the handoff, with a person still owning the decision. For agencies dealing with public comment or permit intake, the same pattern applies, and it's part of our government and public sector work. If your team is already feeling it, tell us what's coming in.
We build alongside the people doing the work.
Bring us the problem you’re thinking about.