Bland Tofu-1 review: a voice model made for noisy calls. Whatever you use, don't let a stray "yes" cancel anything
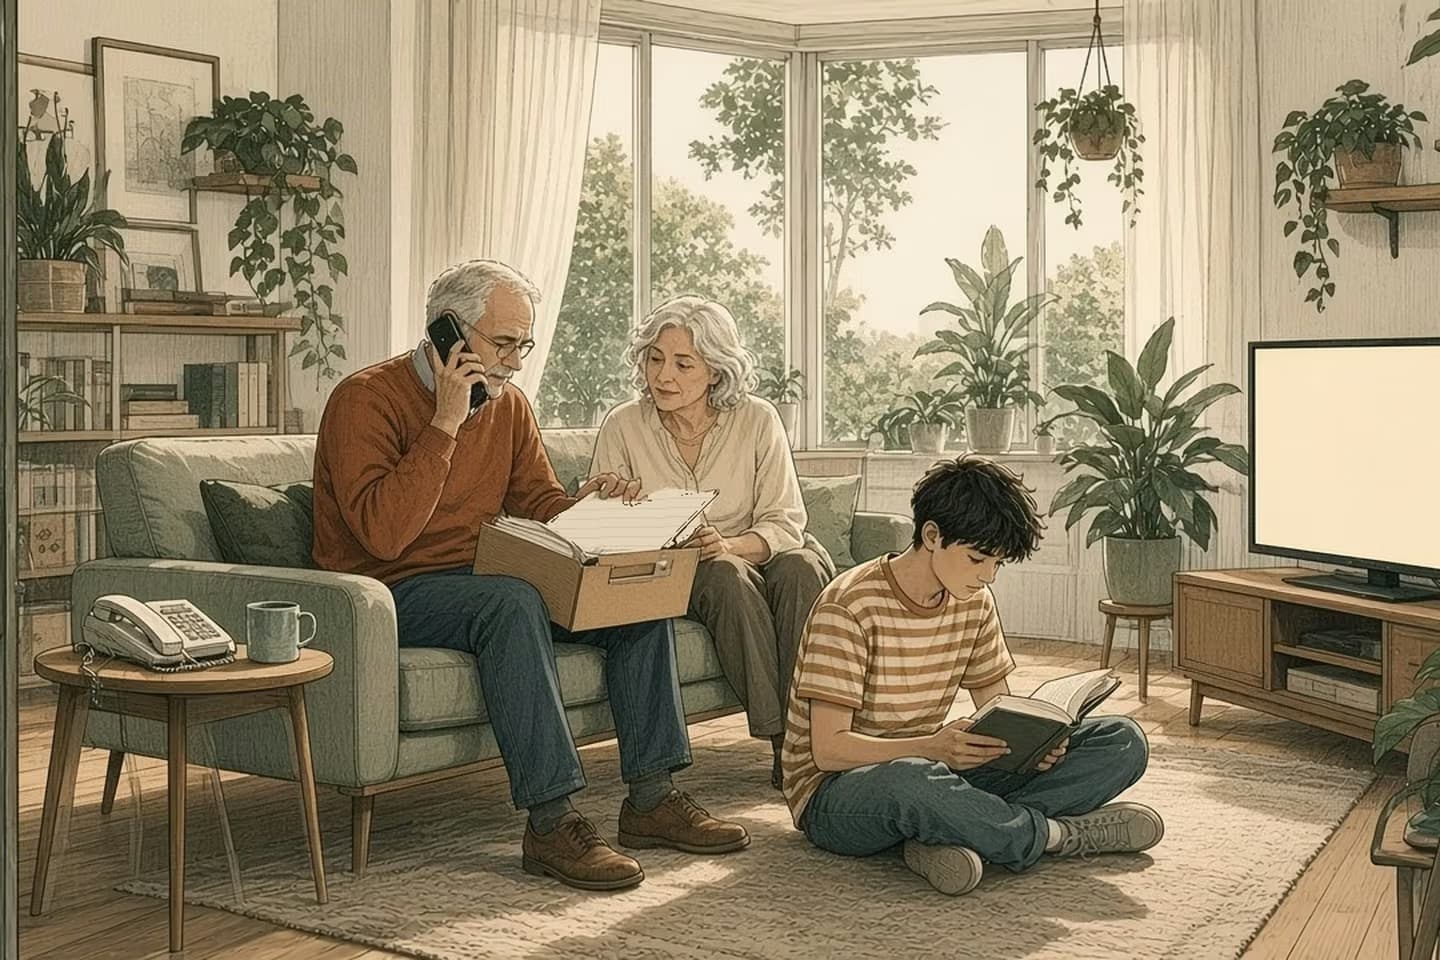
A woman is hunting for her policy number. The agent asks whether she wants to cancel. In the next room a television says "Yes!" Bland's launch page leans on exactly that scene, and it's the cheapest idea in the launch to borrow.
Bland's Tofu-1, announced November 13, 2026, is a speech-to-speech model that listens while it speaks and tries to tell the caller from a television, a child or the line. It's a research preview for a limited number of enterprises, with no published pricing or benchmark numbers. Don't plan to buy it this month. Do copy its test: any phone agent should confirm an irreversible step in a way a stray voice can't answer.
What Bland announced
On November 13, Bland, a company that builds phone agents, published a page for Tofu-1, which it calls a full-duplex speech-to-speech model built for "the calls where conditions are worst and mistakes cost the most." Think calls from a moving car or a hospital room, over weak signal, with several people talking at once.
Bland's argument is about how most voice agents are built today. Many are cascades: they turn speech into text, hand the text to a language model and turn the reply back into speech. Bland says each step throws something away, such as who was speaking, who they were speaking to, whether they hesitated and whether they'd finished. Tofu-1 listens to the audio itself, which Bland says keeps those clues available. It listens and speaks at the same time, so a caller can interrupt or correct it, and it can keep working on a request, such as looking something up, while it talks. Bland also says it never reports a task as done before it is.
It can tell speakers apart, work out who a phrase is meant for, and separate speech from a crying child, a television, traffic, a hospital intercom or keypad tones. Bland says it also hears hesitation, frustration and urgency. And because it models the sound of a call, it can generate one, with a second speaker and the room around them. Bland's samples were produced that way.
The television test
One scene on Bland's page is the clearest explanation of the whole idea. The agent asks, "Just to confirm, you want to cancel your policy?" The caller says nothing, because she's looking for her policy number. In the room, a television says, "Yes!" A transcript-based agent can treat that as her answer and cancel. Bland says Tofu-1 is built to attribute the "yes" to the television and ask the caller to confirm.
Bland labels this an illustrative scenario, not a recorded model output. So it describes the problem Bland wants to solve, not evidence that Tofu-1 solves it. The page also states a limit: if the background makes the caller impossible to understand, Tofu-1 should say so and ask her to repeat herself or move somewhere quieter, and ignoring the television must never become a reason to guess.
We think that scene is worth more than the model. It's a test any owner can borrow, whatever phone agent they use or plan to. A phone agent should never cancel anything because a television said yes.
Sequence of work
The television test, as Bland describes it
- The agent asks
"Just to confirm, you want to cancel your policy?"
- The caller says nothing
She is still looking for her policy number.
- The television answers
"Yes!", as clear as any caller would say it.
- A transcript-based agent
Can take the "yes" as her answer and cancel.
- Tofu-1, per Bland
Is built to attribute the "yes" to the television and ask the caller to confirm.
A phone agent should never cancel anything because a television said yes.
Who it's for, and what's missing
Bland says it wants teams that handle high-stakes calls in banking, healthcare, insurance and government. Access is a research preview for a limited number of enterprises, and the request form asks for a work email, a phone number and a monthly call-volume band that starts below 1,000 calls and tops out at 50,000 or more. If you're a small business with a front desk and a voicemail box, you aren't the audience yet.
If you do request access, go in with questions, not just a volume band. Where does the call audio go, and how long is it kept? What does the agent do when it can't tell who is speaking, and how does it say so? How does a call move to a person, and what does that person see? What gets logged when it does something on the account? Bland's own page tells you the problem it's aiming at. Your questions will tell you how far along the answer is, and how candid the company is about the parts that aren't finished.
What isn't published matters for anyone weighing it. IT Post's write-up of the launch notes that Bland hasn't published pricing, parameter counts, formal API documentation or a general-availability date, and Nvdium reports no public benchmark figures for latency or word-error rate. Nvdium also reports that the launch video was fully synthetic, that the founder acknowledged "pretty serious security concerns" while testing is finished, and that a smaller version is planned for early December. Those last details come from one outlet, so treat them as reported, not confirmed.
How it compares
The comparison that matters is with what you'd use instead: a conventional voice agent built from speech recognition, a language model and a voice. That approach is widely available, and many teams can tune each piece. The trade-off Bland describes is real: more places for information to get lost. What Tofu-1 offers is one model that hears the whole call. What it costs, and how well it does in practice, nobody outside the preview can say yet.
The other alternative is not to rely on voice for anything that can't be undone. A text message with a link, a code read back, a keypad press or a callback to the number on file all get a clear yes from the person on the account, in a form a television can't produce. We'd use one of those for any cancellation, payment or change of address, whichever model sits behind the phone. We covered the payment case in before your phone agent takes a card, and the question of what a summary drops in what an AI call summary leaves out.
Decision guide
Two ways to build a phone agent
| Consideration | Speech to text, then a language model, then speech | Tofu-1: one speech-to-speech model |
|---|---|---|
| What the model hears | A transcript of the words | The audio itself, including who spoke and how |
| Interruptions | Handled around the model | Listens while it speaks, so a caller can correct it mid-sentence |
| Background voices | Easily become part of the request | Built to attribute them to another source |
| Availability | Widely available | Research preview for a limited number of enterprises |
| Published pricing | Varies by vendor | None found |
Plain verdict
Don't plan around Tofu-1 this month. It's a preview, there's no price, no published benchmark and no general release. If you're a bank, insurer, health system or agency with real call volume, the request form is open and worth filling in, with questions ready about security, call recording and where the audio goes.
For everyone else, take the scene, not the product. List every action your phone agent, or your human staff, can take on a call that can't be undone. For each, decide how it's confirmed in a way a stray voice can't supply. Then play a recording of your own noisy call to the agent and see what it does.
If you're building or buying a voice agent and want help designing those confirmation steps and the handoff to a person, that's our AI applications and agents work. Talk to us.
Related work: Spin:Market
We build alongside the people doing the work.
Bring us the problem you’re thinking about.