The TWIMCO notebook
Field notes.
Useful observations from inside the work.
For people building a better way.
AI & judgment · 12 notes
Opening note / AI & judgment
Let AI draft your review replies. Read the angry ones yourself.
Replying to every review takes time nobody has, and plenty of tools now offer to do it for you. For the five-star thank-yous, that's fine. For the customer describing a bad evening in detail, a smooth automatic reply can make things worse in public.
Read the note ↗︎
A forecast that gives you one number is hiding the useful part.
"Can the AI just tell me how much to order?" It's the question we hear most from owners looking at demand forecasting. Here's roughly how the conversation goes, and why the answer we give is about ranges, sold-out days and who makes the call.
Read the note ↗︎
The AI summary dropped the one thing the customer said twice.
"Customer happy, wants to renew, send quote." It reads well, it's mostly true, and it leaves out the condition the whole renewal depends on. Reading one call against its summary, line by line, shows what to ask these tools for and what a person still has to check.
Read the note ↗︎
Anthropic's human-review rule isn't new. Now it's spelled out.
If your Claude-powered screener tells someone they don't qualify, a qualified person was always supposed to see that first. Anthropic's October 8 rewrite makes the rule much harder to miss.
Read the note ↗︎
Your team already uses AI. Write the policy for that team.
If the policy says no AI and people are pasting customer emails into a chatbot on their phones, the policy isn't working. These are the questions worth answering before you write one more rule.
Read the note ↗︎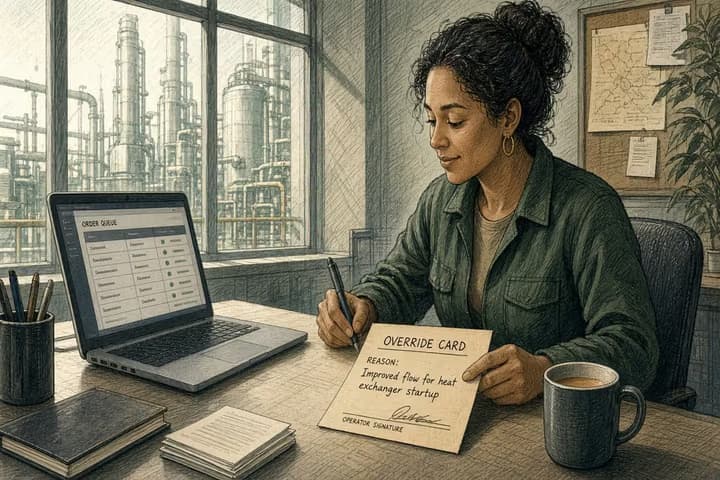
An override without a reason is a silent decision.
A person disagrees with the agent, edits the value and moves on. Now the record shows only the final answer, and later nobody can tell judgment from a glitch. When someone overrides an automation, the original and the reason should both stay.
Read the note ↗︎
Do you need a model, or a rule nobody wrote down?
A lot of "we need AI for this" turns out to be a rule nobody has written down yet. Here's how to tell which one you're looking at, and what it looks like when a model really earns its place.
Read the note ↗︎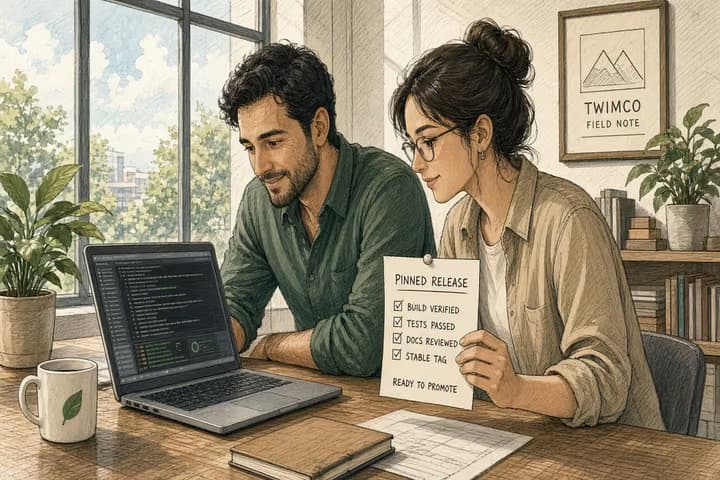
Do not promote what you cannot pin.
Since last week's convincing demo, the model alias moved, the prompt was edited in a console and a tool gained a parameter. What you're about to promote isn't what was reviewed. Write down exactly what will run, and stop if any of it drifts.
Read the note ↗︎
Decide what the agent may log before the first trace.
The first trace is already too late if you have not decided what stays, what gets masked, and who is allowed to unmask it.
Read the note ↗︎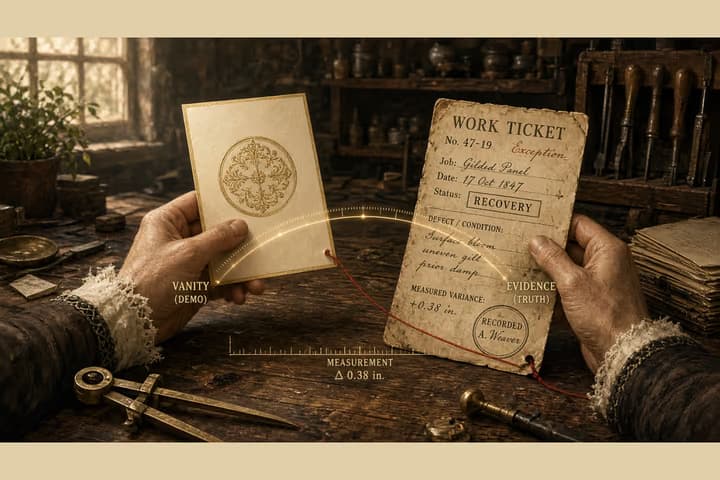
Measure operational AI by the work, not the demo.
Token counts and thumbs-up ratings flatter a demo. For an agent doing real work, ask plainer things. Did the record show the job finished? What happened when it stopped halfway? Have its permissions quietly grown?
Read the note ↗︎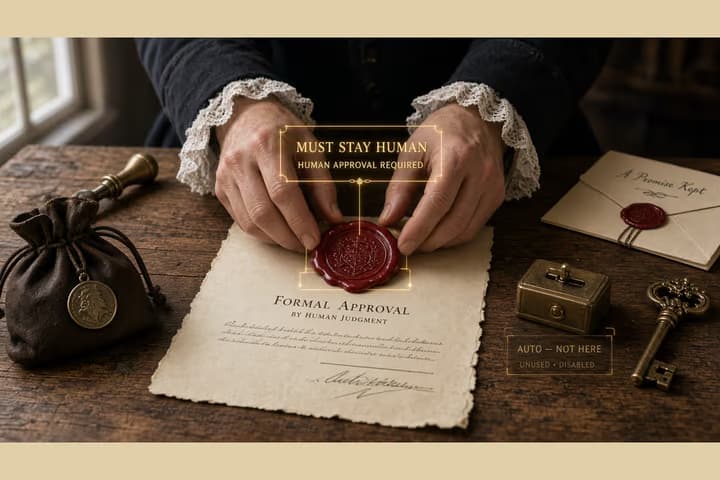
Some approvals should stay human.
When every agent action needs a human yes, people turn into slow middleware, and someone proposes removing the approvals altogether. Both go wrong. Some gates, like moving money or making a promise you can't take back, should stay with a person.
Read the note ↗︎
An agent needs a job, not a personality.
Start with a responsibility, a boundary, and a way to tell whether the work was done well.
Read the note ↗︎A familiar problem? Let’s look closer.
Tell us where you want to go. We’ll find the first thing worth changing.
Tell us about it ↗︎